Vercel AI
 OpenAI
 Anthropic
 Google Gen AI
 LangChain
 LangGraph
 Mastra
 Pydantic AI
 LiteLLM
 Hugging Face
 Workers AI
 Eve
 Flue
 Laravel AI
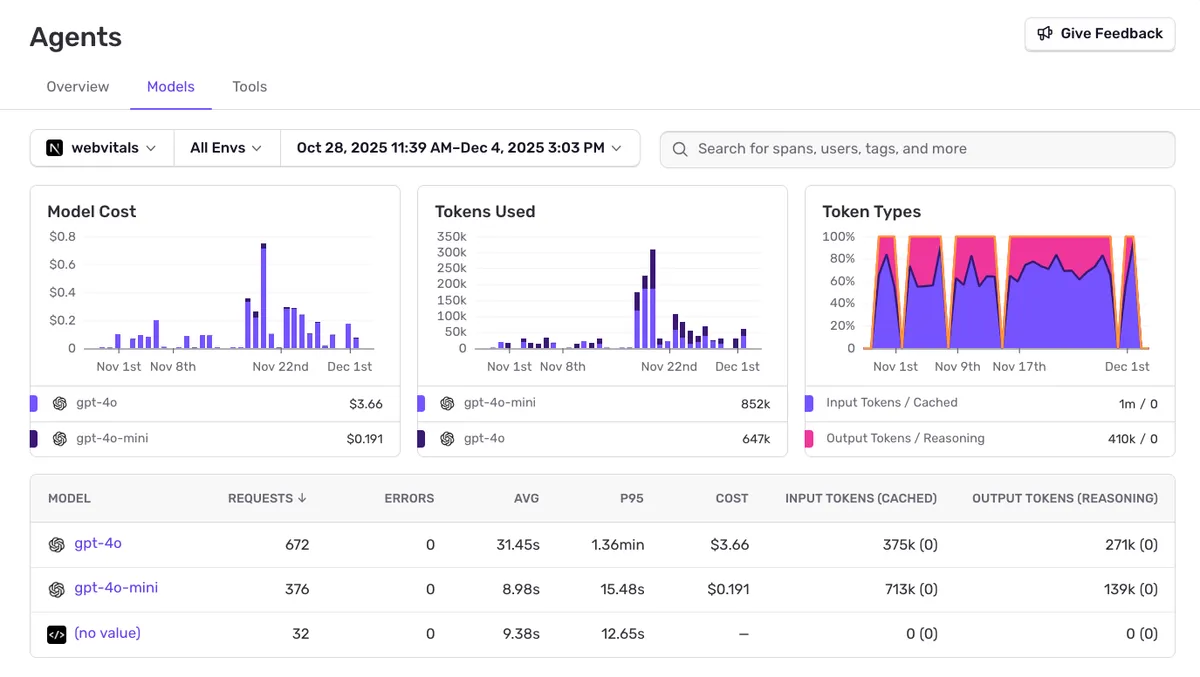
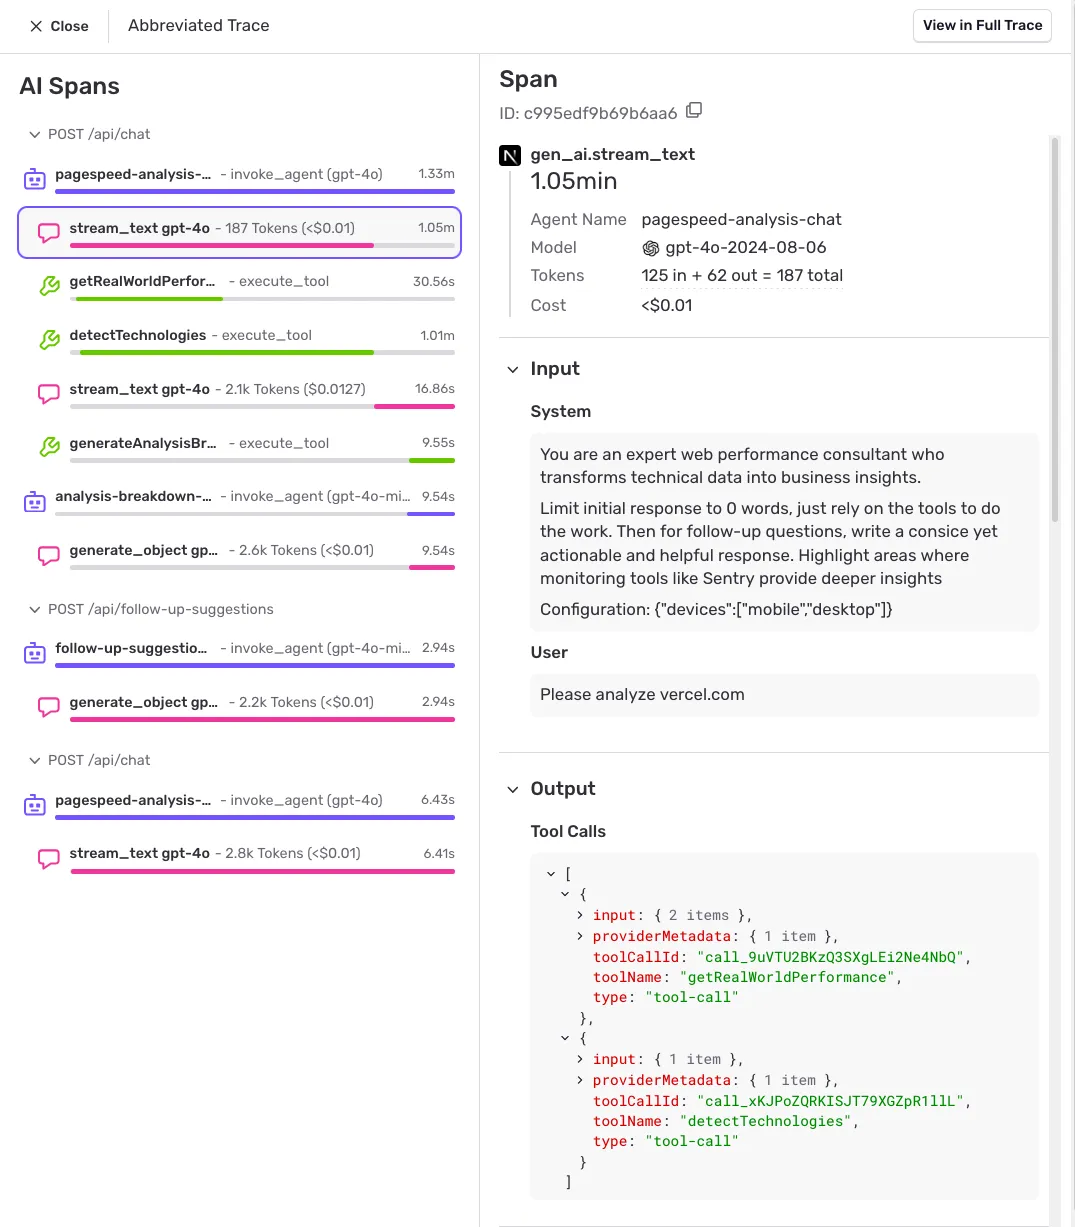
LLM monitoring in Sentry tracks every LLM call, agent run, and tool call in production with errors, latency, and token cost, tied to the code that triggered it. Each call is captured as a trace with full prompt and response context, so you can debug failures and optimize performance without leaving your application monitoring. See how to monitor AI agent costs in Next.js.
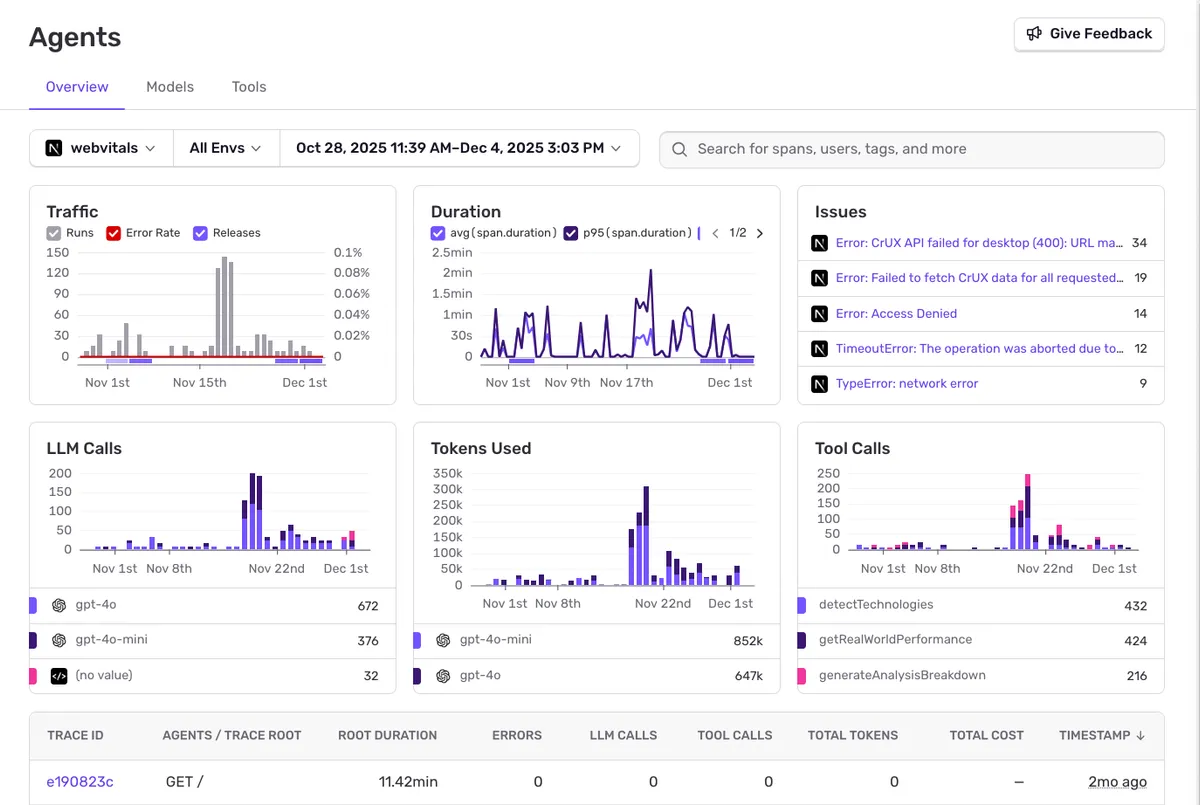
Track all agent runs, error rates, LLM calls, tokens used, and tool executions. Monitor traffic patterns and duration metrics across your AI-powered features.