

Bounding Box Prediction is a computer vision technique used to detect and locate objects within an image by drawing rectangular boxes around them. Unlike image classification, which only identifies the object, it also determines the object's position and size within the image.
- Predicts the location of objects using bounding box coordinates.
- Supports detection of multiple objects in a single image.
- Provides both object classification and localization.
- Widely used in object detection applications.
Working of Bounding Box Prediction
Bounding box prediction follows a sequence of steps to detect and localize objects in an image.
1. Image Input: The input image is loaded into the system for processing.
2. Image Preprocessing: The image is converted into a tensor and transformed into a format suitable for the deep learning model.
3. Feature Extraction: A Convolutional Neural Network (CNN) extracts important features such as edges, textures and object shapes.
4. Bounding Box Prediction: The object detection model predicts:
- Bounding box coordinates
- Confidence scores
- Object class labels
5. Filtering Predictions: Predictions with confidence scores below a specified threshold are removed.
6. Object Localization: Bounding boxes and labels are drawn on the image to indicate detected objects.
Implementation
This implementation uses the pre-trained SSD300 VGG16 object detection model available in PyTorch.
1. Import Required Libraries
- torch provides deep learning functionality from Pytorch.
- torchvision provides pre-trained computer vision models.
- transforms is used for image preprocessing.
- cv2 is used for image handling and visualization.
import torch
import torchvision
from torchvision import transforms as T
import cv2
2. Load the Pre-trained SSD Model
- SSD (Single Shot Multibox Detector) performs object detection in a single forward pass.
- model.eval() sets the model to evaluation mode for inference.
model = torchvision.models.detection.ssd300_vgg16(
    pretrained=True
)

model.eval()
3. Define Class Names
- Stores object class names used for labeling detected objects.
- These correspond to the labels predicted by the model.
classnames = [
    "person","bicycle","car","motorcycle","airplane",
    "bus","train","truck","boat","traffic light",
    "fire hydrant","stop sign","parking meter",
    "bench","bird","cat","Dog","horse","sheep",
    "cow"
]
4. Load and Transform the Image
- load_image() reads the image using OpenCV.
- transform_image() converts the image into a PyTorch tensor.
def load_image(image_path):

    return cv2.imread(image_path)


def transform_image(image):

    return T.ToTensor()(image)
5. Detect Objects
- Performs object detection using the SSD model.
- Extracts bounding boxes, confidence scores and labels.
- Keeps only predictions above the confidence threshold.
def detect_objects(
        model,
        image_tensor,
        confidence_threshold=0.80):

    with torch.no_grad():

        predictions = model(
            [image_tensor]
        )

    bbox = predictions[0]["boxes"]
    scores = predictions[0]["scores"]
    labels = predictions[0]["labels"]

    indices = torch.nonzero(
        scores > confidence_threshold
    ).squeeze(1)

    return (
        bbox[indices],
        scores[indices],
        labels[indices]
    )
6. Draw Bounding Boxes and Labels
- Draws rectangles around detected objects.
- Retrieves the corresponding class name.
- Displays the label above the bounding box.
def draw_boxes_and_labels(
        image,
        bbox,
        labels,
        class_names):

    img_copy = image.copy()

    for i in range(len(bbox)):

        x1, y1, x2, y2 = (
            bbox[i]
            .numpy()
            .astype("int")
        )

        cv2.rectangle(
            img_copy,
            (x1, y1),
            (x2, y2),
            (0, 0, 255),
            3
        )

        class_name = class_names[
            labels[i].item() - 1
        ]

        cv2.putText(
            img_copy,
            class_name,
            (x1, y1 - 10),
            cv2.FONT_HERSHEY_SIMPLEX,
            1,
            (0, 255, 0),
            2
        )

    return img_copy
7. Perform Detection and Display Output
- Loads the input image.
- Converts it into a tensor.
- Detects objects using the SSD model.
- Draws bounding boxes and labels.
- Displays the final output image.
img = load_image(
    "Image path"
)

img_tensor = transform_image(
    img
)

bbox, scores, labels = detect_objects(
    model,
    img_tensor
)

result_img = draw_boxes_and_labels(
    img,
    bbox,
    labels,
    classnames
)

cv2_imshow(result_img)
Output:
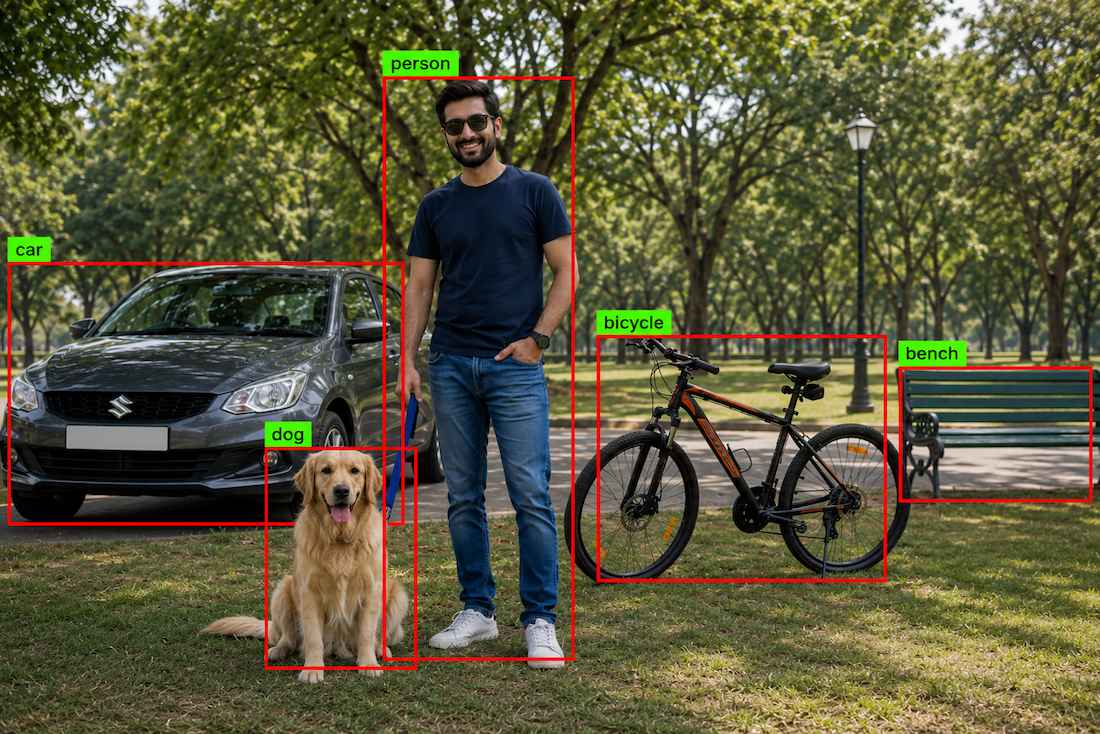
Download full code from here
Applications
- Bounding box detection helps autonomous vehicles identify pedestrians, vehicles, traffic signs, and other obstacles to support safe navigation.
- It is widely used in surveillance systems to detect, track, and monitor people or objects in real time.
- In retail analytics, it helps track products, manage inventory, and analyze customer behavior within stores.
- In medical imaging, it assists in locating abnormalities, tumors, or specific structures for diagnosis and treatment planning.
- Robotics systems use bounding box detection to identify and locate objects for tasks such as navigation and object manipulation.
- It is also used in sports analytics to track players, equipment, and movements for performance analysis.
