

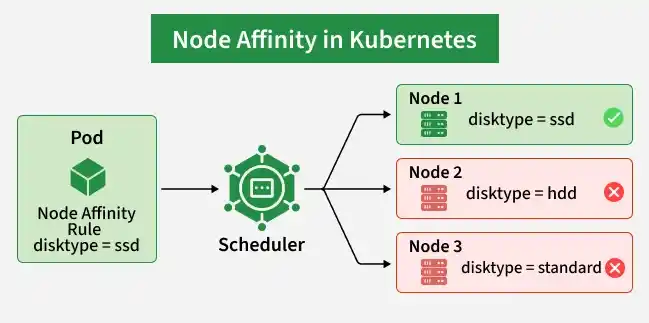
Node Affinity in Kubernetes controls where Pods are scheduled by using labels and rules defined for Nodes. It helps place Pods on suitable Nodes based on specific requirements.
- Node Selection allows Pods to be scheduled on Nodes with specific labels.
- Node Attributes can be used to select Nodes based on factors such as CPU, memory, region, or data center.
- Preferred Rules allow Pods to prefer certain Nodes without making the requirement mandatory.
- Anti-Affinity Rules help avoid scheduling Pods on specific Nodes.
- Complex Rules allow flexible Pod placement strategies based on multiple Node labels and conditions.
How Node Affinity Works
Node Affinity works by matching the labels of Nodes with the rules defined in a Pod specification.
For example, a Node can have the following label:
kubectl label nodes node-1 disktype=ssdThe Node now has:
disktype=ssdA Pod can then specify that it should run on a Node with this label.
affinity:
  nodeAffinity:
    requiredDuringSchedulingIgnoredDuringExecution:
      nodeSelectorTerms:
        - matchExpressions:
            - key: disktype
              operator: In
              values:
                - ssd
The scheduler checks the available Nodes and selects a Node whose labels match the defined rule.
Types of Node Affinity
Kubernetes provides two main types of Node Affinity.
1. Required Node Affinity
requiredDuringSchedulingIgnoredDuringExecution defines a mandatory rule for scheduling.
The Pod will only be scheduled on a Node that satisfies the specified affinity rules.
affinity:
  nodeAffinity:
    requiredDuringSchedulingIgnoredDuringExecution:
      nodeSelectorTerms:
        - matchExpressions:
            - key: disktype
              operator: In
              values:
                - ssd
If no Node satisfies the rule, the Pod remains unscheduled.
2. Preferred Node Affinity
preferredDuringSchedulingIgnoredDuringExecution defines a preference rather than a strict requirement.
The scheduler gives higher priority to Nodes that satisfy the rule, but the Pod can still be scheduled on another suitable Node if the preferred Node is unavailable.
affinity:
  nodeAffinity:
    preferredDuringSchedulingIgnoredDuringExecution:
      - weight: 80
        preference:
          matchExpressions:
            - key: disktype
              operator: In
              values:
                - ssd
The weight value determines how strongly the scheduler should prefer the matching Node.
Required vs Preferred Node Affinity
| Feature | Required | Preferred |
|---|---|---|
| Rule | Mandatory | Preference |
| Matching Node | Required | Preferred |
| If no match | Pod remains unscheduled | Pod can use another Node |
| Field | requiredDuringSchedulingIgnoredDuringExecution | preferredDuringSchedulingIgnoredDuringExecution |
| Use case | Strict placement | Flexible placement |
Difference Between Node Selector And Node Affinity
In Kubernetes, the concepts of node selector and node affinity are used to control the scheduling of pods onto the required cluster nodes.
Node Selector
- Used for simple Node selection.
- Matches Pods with specific Node labels.
- Suitable for small clusters and basic scheduling requirements.
Node Affinity
- Used for advanced Node selection.
- Supports complex rules based on Node labels.
- Supports preferred and required scheduling rules.
- Can also define anti-affinity rules to avoid specific Nodes.
- Suitable for larger clusters requiring precise Pod placement.
So basically, Node Selector provides an easy method for choosing nodes based on labels, whereas Node Affinity offers more advanced capabilities for choosing and avoiding nodes based on complex rules.
Difference Between Pod Affinity vs Node Affinity
Criteria | Pod Affinity | Node Affinity |
|---|---|---|
Definition | It used for defining rules for Pod's affinity or anti-affinity with other pods. | It used for specifying the rules for pod scheduling based on the node labels. |
Scope | It used for applying pod scheduling decisions within the same node or across different nodes. | It used for influencing the pod scheduling decisions based on node labels. |
Flexibility | It offers the flexibility in affinity or anti-affinity rules between pods. | It provides the flexibility in expressing the preferences or requirements about the node attributes. |
Example | It co-locates the pods of same application on the same node for improved locality. | It used for scheduling pods required GPU's only on node labeled with GPU resources. |
Control | It operates at the pod level, allowing fine-grained control over pod placement decisions. | It operates at the node level, influencing the pod scheduling based on node labels. |
Use Cases | It ensure co-location or anti co-location of related pods on the same or different nodes. | It specifies the rules for pod scheduling based on the node labels. |
Advantages
The following are the advantages of Kubernetes Node Affinity:
- Node affinity aids Kubernetes clusters in making better use of their resources by ensuring that pods are scheduled on nodes that have the necessary resources. The performance of the application can be improved in this way.
- It gives Kubernetes administrators more control over the placement of their pods, which can be extremely beneficial for applications that require specific hardware or network resources.
- By ensuring that pods are scheduled on particular nodes or groups of nodes, node affinity can improve the availability of applications in Kubernetes clusters.
Disadvantages
The following are the disadvantages of Kubernetes Node Affinity:
- It can significantly increase the complexity of Kubernetes clusters, especially for administrators who are unfamiliar with the platform. It might be difficult to solve problems or maximize resource use as a result.
- Node affinity increases Kubernetes clusters' overhead costs by allowing for more configuration and maintenance than just letting the scheduler distribute pods as it sees fit.
- It can also limit the scalability of Kubernetes clusters due to its ability to scale up or down or add new nodes to the cluster. It might be difficult or time-consuming to add new nodes that meet the same criteria.
Difference of Pod Affinity, Intra-pod Affinity and Anti-Affinity
The following are the difference of pod affinity, Intra-pod affinity and Anti-Affinity:
| Feature | Pod Affinity | Intra-Pod Affinity | Pod Anti-Affinity |
|---|---|---|---|
| Definition | Schedules related pods together. | Controls container placement within a pod. | Spreads pods across nodes. |
| Use Case | Improves communication between related pods. | Places dependent containers together or apart. | Improves fault tolerance. |
| Example | Places frontend and backend pods on the same node. | Places containers requiring fast communication together. | Spreads service replicas across nodes. |
| Kubernetes API | podAffinity | Not applicable | podAntiAffinity |
How to Assign Pods to Nodes Using Node Affinity
Assigning the pods to Nodes using the node affinity provides the control on which nodes our pods to be scheduled, based on the node labels. The following is the step by step guide for assigning the pods to nodes using node affinity:
Step 1: Firstly ensure that the kubernetes cluster is in running state with kubernetes master and worker nodes.
Step 2: Create label the nodes with their specifications so that we can make easier to deploy pods on where we want to deploy. The following command helps in setting the labels to the nodes.
kubectl label nodes <node-names> <label-key>=<label-value>Step 3: Define the node affinity in Pod Yaml. In you pod manifest file, try to define the node affinity rules under the spec section. The following is an example of Yaml code:
spec:
  affinity:
    nodeAffinity:
      requiredDuringSchedulingIgnoredDuringExecution:
        nodeSelectorTerms:
        - matchExpressions:
          - key: <label-key>
            operator: In
            values:
            - <label-value>
Step 4: Apply the pod configuration: After once defining the affinity rules save the yaml configuration file and apply it using the following command:
kubectl apply -f <file_name.yaml>Step 5: Verify Pod Placement: Verify where the pod is placement on the Node with the following command;
kubectl get pods -o wideAdding A Label to a Node
On adding the labels to the nodes provides to specify additional metadata to the node, which can be used for various purposes like node selection, scheduling and grouping.
- The following command is used for adding label to the node:
kubectl label nodes <node-name> <label-key>=<label-value>- Verify the labels of the node with the following command:
# Add Label to Node
kubectl label nodes <node-name> <label-key>=<label-value>
Schedule A Pod Using Required Node Affinity
The following are the steps for sechule a pod using required Node Affinity:
Step 1: Identiy the Node Label: Firstly identify the node on which you want to deploy the pod, know its node labels.
Step 2: Deine Pod Yaml: Create a pod yaml manifest with the required node affinity specified rules under the spec section.
# Define Pod YAML with Required Node Affinity
apiVersion: v1
kind: Pod
metadata:
  name: pod-with-required-affinity
spec:
  affinity:
    nodeAffinity:
      requiredDuringSchedulingIgnoredDuringExecution:
        nodeSelectorTerms:
        - matchExpressions:
          - key: <label-key>
            operator: In
            values:
            - <label-value>
  containers:
  - name: example-container
    image: nginx:latest
Step 3: Apply Pod Configuration: After once configured and defined the affinity rules in the yaml manifest file save it and then apply the changes with the following command:
kubectl apply -f pod-with-required-affinity.yaml Step 4: Verify Pod Placement: Now, check the pod is scheduled on a node with the specified label using the following command:
kubectl get pods -o wideSchedule a Pod Using Preferred Node Affinity
The following are the steps for scheduling the pod using preferred Node Affinity:
Step 1: Identify the Node Label: Firstly identify the node on which you want to deploy the pod, know its node labels.
Step 2: Define Pod Yaml: Create a pod manifest Yaml with preferred node affinity specified under the spec section.
# Define Pod YAML with Preferred Node Affinity
apiVersion: v1
kind: Pod
metadata:
  name: pod-with-preferred-affinity
spec:
  affinity:
    nodeAffinity:
      preferredDuringSchedulingIgnoredDuringExecution:
      - weight: 1
        preference:
          matchExpressions:
          - key: <label-key>
            operator: In
            values:
            - <label-value>
  containers:
  - name: example-container
    image: nginx:latest
Step 3: Apply Pod Configuration: Using the following command you can apply the pod configuration:
kubectl apply -f pod-with-preferred-affinity.yamlStep 4: Verify the Pod Placement: Check the pod scheduled on a node with the specified labels using the following command:
kubectl get pods -o wideAssigning Pods to Nodes
The following are the steps for assigning the pods to nodes:
Step 1: Label the Nodes: Firstly Identify the node where you want to schedule th pods and provide the labels to the node with the following command:
kubectl label nodes node-1 environment=productionStep 2: Create Pod Yaml File: Now, Create pod manefist file to schedule the pod on the specific labeled node. The pod manifest file looks as follows:
apiVersion: v1
kind: Pod
metadata:
  name: my-pod
spec:
  containers:
  - name: my-container
    image: nginx
  affinity:
    nodeAffinity:
      requiredDuringSchedulingIgnoredDuringExecution:
        nodeSelectorTerms:
        - matchExpressions:
          - key: environment
            operator: In
            values:
            - production
Step 3: Apply Configuration: Once, you configured the pod manefist file, use the following command to apply the configuration:
kubectl apply -f pod.yamlStep 4: Verify Pod Placement: Check the pod is scheduled on the desired node using the following command:
kubectl get pods -o wideCommand to See Existing labels of the Node
The following is the command used to see the existing labels of the Node:
kubectl get nodes --show-labelsCommand to set New Labels to Node
The following is the command used to set the new labels to the Node:
kubectl label nodes <node-name> <label-key>=<label-value>Example of NodeAffinity
You must include the selector rules in the pod's YAML definition file in order to use the node selector in Kubernetes. For example, the YAML file below defines a pod with a necessary node selector for nodes with the label "nginx"

In the following example, we have used the 'nodeSelector' parameter for showing the required node affinity for nodes that do have the label 'nginx'. This means that the pod will be scheduled on the nodes which contain this label.
Let's take another example of Node Affinity. For this, we will first create a deployment. The deployment will have the following features:
- name: Blue
- image: nginx
- replicas: 3
In order to create this deployment we can use two different approaches. However, for simplicity, we will use an imperative approach. We can create this deployment using the command:

To check whether or not the deployment was created successfully, execute the command:
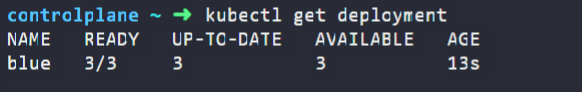
We have two nodes in my cluster, the control plane, and node01.

For this example, we want to Set Node Affinity to the deployment to place the pods on node01 only.
- Name of the deployment: blue
- Replicas: 3
- Image: nginx
- NodeAffinity: requiredDuringSchedulingIgnoredDuringExecution
- Key: color
- value: blue
In order to achieve this, we will edit the deployment using:

Once we are in we will add the following block of script on the same level of container:

- spec Defines the Pod configuration and its scheduling rules.
- affinity Contains the Pod's scheduling preferences, including
nodeAffinity. - requiredDuringSchedulingIgnoredDuringExecution Requires the Pod to match the specified Node rules during scheduling. Changes to Node labels do not reschedule a running Pod.
- nodeSelectorTerms Defines the Node requirements for scheduling.
- matchExpressions Matches Node labels using operators such as
In. Here,color=blueis required. - Result The Pod is scheduled on
node01, which has the matching label. Verify it using the required command.

