

Given a string s and a list dictionary[] of words. Find whether the string s can be formed by concatenating one or more words from the dictionary[].
Note: From dictionary[], any word can be taken any number of times and in any order.
Examples:
Input: s = "ilike", dictionary[] = ["i", "like", "gfg"]
Output: true
Explanation: s can be breakdown as "i like".Input: s = "ilikegfg", dictionary[] = ["i", "like", "man", "india", "gfg"]
Output: true
Explanation: s can be breakdown as "i like gfg".Input: s = "ilikemangoes", dictionary[] = ["i", "like", "man", "india", "gfg"]
Output: false
Explanation: s cannot be formed using dictionary[] words.

Table of Content
[Naive Approach] Trying All Prefixes - O(2^n) Time and O(n) Space
The idea is to try every possible prefix of the string.
- If a prefix is present in the dictionary, we recursively solve for the remaining string.
- If the remaining string can be broken, the whole string can be broken.
Base Case: If the string becomes empty, all its characters have been matched, return true.
Working of the Approach:
- Store all dictionary words in a hash set for O(1) average lookups.
- If the string is empty, return true, as every character has been matched.
- For each index i from 1 to n, take the prefix s[0..i).
- If this prefix is present in the set, recursively check the remaining string s[i..n).
- If any recursive call returns true, return true immediately.
- If no prefix leads to a valid break, return false.
#include <iostream>
#include <vector>
#include <string>
#include <unordered_set>
using namespace std;

bool wordBreakRec(string s, unordered_set<string> &st) {

    // base case: the whole string is matched
    if (s.empty())
        return true;

    int n = s.length();

    // try every prefix s[0..i)
    for (int i = 1; i <= n; i++) {
        string prefix = s.substr(0, i);

        // if the prefix is a dictionary word, check the remaining string
        if (st.count(prefix) && wordBreakRec(s.substr(i), st))
            return true;
    }

    // no valid break found
    return false;
}

bool wordBreak(string &s, vector<string> &dictionary) {

    // store all dictionary words in a set for fast lookups
    unordered_set<string> st(dictionary.begin(), dictionary.end());

    return wordBreakRec(s, st);
}

int main() {
    string s = "ilike";
    vector<string> dictionary = {"i", "like", "gfg"};

    cout << (wordBreak(s, dictionary) ? "true" : "false") << endl;
    return 0;
}
import java.util.Arrays;
import java.util.HashSet;

class GFG {

    static boolean wordBreakRec(String s, HashSet<String> st) {

        // base case: the whole string is matched
        if (s.isEmpty())
            return true;

        int n = s.length();

        // try every prefix s[0..i)
        for (int i = 1; i <= n; i++) {
            String prefix = s.substring(0, i);

            // if the prefix is a dictionary word, check the remaining string
            if (st.contains(prefix) && wordBreakRec(s.substring(i), st))
                return true;
        }

        // no valid break found
        return false;
    }

    static boolean wordBreak(String s, String[] dictionary) {

        // store all dictionary words in a set for fast lookups
        HashSet<String> st = new HashSet<>(Arrays.asList(dictionary));

        return wordBreakRec(s, st);
    }

    public static void main(String[] args) {
        String s = "ilike";
        String[] dictionary = {"i", "like", "gfg"};

        System.out.println(wordBreak(s, dictionary));
    }
}
def wordBreakRec(s, st):

    # base case: the whole string is matched
    if len(s) == 0:
        return True

    n = len(s)

    # try every prefix s[0..i)
    for i in range(1, n + 1):
        prefix = s[:i]

        # if the prefix is a dictionary word, check the remaining string
        if prefix in st and wordBreakRec(s[i:], st):
            return True

    # no valid break found
    return False


def wordBreak(s, dictionary):

    # store all dictionary words in a set for fast lookups
    st = set(dictionary)

    return wordBreakRec(s, st)


if __name__ == "__main__":
    s = "ilike"
    dictionary = ["i", "like", "gfg"]

    print("true" if wordBreak(s, dictionary) else "false")
using System;
using System.Collections.Generic;

class GFG {

    static bool wordBreakRec(string s, HashSet<string> st) {

        // base case: the whole string is matched
        if (s.Length == 0)
            return true;

        int n = s.Length;

        // try every prefix s[0..i)
        for (int i = 1; i <= n; i++) {
            string prefix = s.Substring(0, i);

            // if the prefix is a dictionary word, check the remaining string
            if (st.Contains(prefix) && wordBreakRec(s.Substring(i), st))
                return true;
        }

        // no valid break found
        return false;
    }

    static bool wordBreak(string s, string[] dictionary) {

        // store all dictionary words in a set for fast lookups
        HashSet<string> st = new HashSet<string>(dictionary);

        return wordBreakRec(s, st);
    }

    static void Main() {
        string s = "ilike";
        string[] dictionary = {"i", "like", "gfg"};

        Console.WriteLine(wordBreak(s, dictionary) ? "true" : "false");
    }
}
function wordBreakRec(s, st) {

    // base case: the whole string is matched
    if (s.length === 0)
        return true;

    let n = s.length;

    // try every prefix s[0..i)
    for (let i = 1; i <= n; i++) {
        let prefix = s.substring(0, i);

        // if the prefix is a dictionary word, check the remaining string
        if (st.has(prefix) && wordBreakRec(s.substring(i), st))
            return true;
    }

    // no valid break found
    return false;
}

function wordBreak(s, dictionary) {

    // store all dictionary words in a set for fast lookups
    let st = new Set(dictionary);

    return wordBreakRec(s, st);
}

// Driver Code
let s = "ilike";
let dictionary = ["i", "like", "gfg"];

console.log(wordBreak(s, dictionary) ? "true" : "false");
Output
true
[Better Approach 1] Top-Down DP - O(n * m * L) Time and O(n) Space
The idea is to use memoization on the recursive solution to avoid recomputing the same subproblems.
- Whether the string can be broken starting from index i depends only on i, so we store this result for every index in a 1D array.
- If an index is reached again through a different combination of words, we return the stored result directly instead of recomputing it.
Working of the Approach:
- Create an array dp[] of size n + 1 and initialize it with -1, which means the result is not computed yet.
- If i is equal to or greater than n, return true, as the whole string is matched.
- If dp[i] is not -1, return the stored result.
- Loop through every word of the dictionary and skip it if it is longer than the remaining string.
- If the word matches the string starting from index i, recursively check the remaining string from index i + word length.
- If any recursive call returns true, the string can be broken from index i.
- Store the result in dp[i] and return it.
Let us understand with an example:
Input: s = "ilike", dictionary = ["i", "like", "gfg"]
- wordBreakRec(0): "i" matches -> check index 1, "like" and "gfg" do not match at index 0
- wordBreakRec(1): "like" matches -> check index 5
- wordBreakRec(5): end of the string -> true
- dp[1] = true and dp[0] = true, so the answer is true.
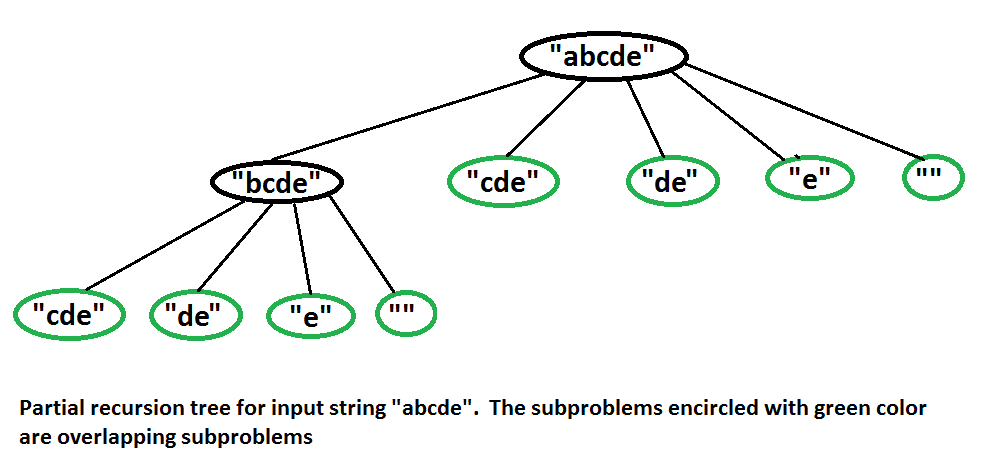
Why Memoization Helps? We can see overlapping subproblems in the following diagram. With memoization, each one is solved at most once, which brings the time down from exponential to O(n * m * L).
#include <iostream>
#include <vector>
#include <string>
using namespace std;

bool wordBreakRec(int ind, string &s, vector<string> &dictionary, vector<int> &dp) {

    // base case: the whole string is matched
    if (ind >= s.size())
        return true;

    // if the result is already computed, return it
    if (dp[ind] != -1)
        return dp[ind];

    bool possible = false;

    // try every word of the dictionary
    for (int i = 0; i < dictionary.size(); i++) {
        string word = dictionary[i];

        // skip the word if it is longer than the remaining string
        if (word.size() > s.size() - ind)
            continue;

        // check if the word matches the string starting from index ind
        bool ok = true;
        int k = ind;
        for (int j = 0; j < word.size(); j++) {
            if (word[j] != s[k]) {
                ok = false;
                break;
            }
            k++;
        }

        // if it matches, check the remaining string
        if (ok)
            possible |= wordBreakRec(ind + word.size(), s, dictionary, dp);
    }

    // store the result before returning
    return dp[ind] = possible;
}

bool wordBreak(string s, vector<string> &dictionary) {
    int n = s.size();
    vector<int> dp(n + 1, -1);
    return wordBreakRec(0, s, dictionary, dp);
}

int main() {
    string s = "ilike";
    vector<string> dictionary = {"i", "like", "gfg"};

    cout << (wordBreak(s, dictionary) ? "true" : "false") << endl;
    return 0;
}
import java.util.Arrays;

class GFG {

    static boolean wordBreakRec(int ind, String s, String[] dictionary, int[] dp) {

        // base case: the whole string is matched
        if (ind >= s.length())
            return true;

        // if the result is already computed, return it
        if (dp[ind] != -1)
            return dp[ind] == 1;

        boolean possible = false;

        // try every word of the dictionary
        for (String word : dictionary) {

            // skip the word if it is longer than the remaining string
            if (word.length() > s.length() - ind)
                continue;

            // check if the word matches the string starting from index ind
            boolean ok = s.startsWith(word, ind);

            // if it matches, check the remaining string
            if (ok)
                possible |= wordBreakRec(ind + word.length(), s, dictionary, dp);
        }

        // store the result before returning
        dp[ind] = possible ? 1 : 0;
        return possible;
    }

    static boolean wordBreak(String s, String[] dictionary) {
        int n = s.length();
        int[] dp = new int[n + 1];
        Arrays.fill(dp, -1);
        return wordBreakRec(0, s, dictionary, dp);
    }

    public static void main(String[] args) {
        String s = "ilike";
        String[] dictionary = {"i", "like", "gfg"};

        System.out.println(wordBreak(s, dictionary));
    }
}
def wordBreakRec(ind, s, dictionary, dp):

    # base case: the whole string is matched
    if ind >= len(s):
        return True

    # if the result is already computed, return it
    if dp[ind] != -1:
        return dp[ind] == 1

    possible = False

    # try every word of the dictionary
    for word in dictionary:

        # skip the word if it is longer than the remaining string
        if len(word) > len(s) - ind:
            continue

        # check if the word matches the string starting from index ind
        ok = s.startswith(word, ind)

        # if it matches, check the remaining string
        if ok:
            possible |= wordBreakRec(ind + len(word), s, dictionary, dp)

    # store the result before returning
    dp[ind] = 1 if possible else 0
    return possible


def wordBreak(s, dictionary):
    n = len(s)
    dp = [-1] * (n + 1)
    return wordBreakRec(0, s, dictionary, dp)


if __name__ == "__main__":
    s = "ilike"
    dictionary = ["i", "like", "gfg"]

    print("true" if wordBreak(s, dictionary) else "false")
using System;

class GFG {

    static bool wordBreakRec(int ind, string s, string[] dictionary, int[] dp) {

        // base case: the whole string is matched
        if (ind >= s.Length)
            return true;

        // if the result is already computed, return it
        if (dp[ind] != -1)
            return dp[ind] == 1;

        bool possible = false;

        // try every word of the dictionary
        foreach (string word in dictionary) {

            // skip the empty word
            if (word.Length == 0)
                continue;

            // skip the word if it is longer than the remaining string
            if (word.Length > s.Length - ind)
                continue;

            // check if the word matches the string starting from index ind
            bool ok = string.CompareOrdinal(s, ind, word, 0, word.Length) == 0;

            // if it matches, check the remaining string
            if (ok)
                possible |= wordBreakRec(ind + word.Length, s, dictionary, dp);
        }

        // store the result before returning
        dp[ind] = possible ? 1 : 0;
        return possible;
    }

    static bool wordBreak(string s, string[] dictionary) {
        int n = s.Length;
        int[] dp = new int[n + 1];
        Array.Fill(dp, -1);
        return wordBreakRec(0, s, dictionary, dp);
    }

    static void Main() {
        string s = "ilike";
        string[] dictionary = {"i", "like", "gfg"};
        Console.WriteLine(wordBreak(s, dictionary) ? "true" : "false");
    }
}
function wordBreakRec(ind, s, dictionary, dp) {

    // base case: the whole string is matched
    if (ind >= s.length)
        return true;

    // if the result is already computed, return it
    if (dp[ind] !== -1)
        return dp[ind] === 1;

    let possible = false;

    // try every word of the dictionary
    for (let word of dictionary) {

        // skip the word if it is longer than the remaining string
        if (word.length > s.length - ind)
            continue;

        // check if the word matches the string starting from index ind
        let ok = s.startsWith(word, ind);

        // if it matches, check the remaining string
        if (ok)
            possible |= wordBreakRec(ind + word.length, s, dictionary, dp);
    }

    // store the result before returning
    dp[ind] = possible ? 1 : 0;
    return possible === true || possible === 1;
}

function wordBreak(s, dictionary) {
    let n = s.length;
    let dp = new Array(n + 1).fill(-1);
    return wordBreakRec(0, s, dictionary, dp);
}

// Driver Code
let s = "ilike";
let dictionary = ["i", "like", "gfg"];

console.log(wordBreak(s, dictionary) ? "true" : "false");
Output
true
[Better Approach 2] Bottom-Up DP - O(n * m * L) Time and O(n) Space
The idea is to use bottom-up dynamic programming to check if the string can be broken into dictionary words. Create a boolean array dp[] of size n + 1, where dp[i] is true if the prefix s[0..i) can be broken into dictionary words.
Working of the Approach:
- Mark dp[0] = true, as an empty prefix is always valid (base case).
- For each position i from 1 to n, check every dictionary word that ends at position i.
- If such a word starts at a position j where dp[j] is true, then dp[i] = true.
- At the end, return dp[n].
#include <iostream>
using namespace std;

bool wordBreak(string &s, vector<string> &dictionary)
{
    int n = s.size();
    vector<bool> dp(n + 1, 0);
    dp[0] = 1;

    // Traverse through the given string
    for (int i = 1; i <= n; i++)
    {

        // Traverse through the dictionary words
        for (string &w : dictionary)
        {

            // Check if current word is present
            // the prefix before the word is also
            // breakable
            int start = i - w.size();
            if (start >= 0 && dp[start] && s.substr(start, w.size()) == w)
            {
                dp[i] = 1;
                break;
            }
        }
    }
    return dp[n];
}

int main()
{
    string s = "ilike";

    vector<string> dictionary = {"i", "like", "gfg"};

    cout << (wordBreak(s, dictionary) ? "true" : "false") << endl;

    return 0;
}
import java.util.*;

class GfG {
    static boolean wordBreak(String s, String[] dictionary)
    {
        int n = s.length();
        boolean[] dp = new boolean[n + 1];
        dp[0] = true;

        // Traverse through the given string
        for (int i = 1; i <= n; i++) {

            // Traverse through the dictionary words
            for (String w : dictionary) {

                // Check if the current word is present and
                // the prefix before the word is also
                // breakable
                int start = i - w.length();
                if (start >= 0 && dp[start]
                    && s.substring(start,
                                   start + w.length())
                           .equals(w)) {
                    dp[i] = true;
                    break;
                }
            }
        }
        return dp[n];
    }

    public static void main(String[] args)
    {
        String s = "ilike";
        String[] dictionary
            = { "i", "like", "gfg" }; // Using String array

        System.out.println(
            wordBreak(s, dictionary) ? "true" : "false");
    }
}
def wordBreak(s, dictionary):
    n = len(s)
    dp = [False] * (n + 1)
    dp[0] = True

    # Traverse through the given string
    for i in range(1, n + 1):

        # Traverse through the dictionary words
        for w in dictionary:

            # Check if current word is present
            # the prefix before the word is also
            # breakable
            start = i - len(w)
            if start >= 0 and dp[start] and s[start:start + len(w)] == w:
                dp[i] = True
                break
    return 1 if dp[n] else 0


if __name__ == '__main__':
    s = "ilike"

    dictionary = ["i", "like", "gfg"]

    print("true" if wordBreak(s, dictionary) else "false")
using System;
using System.Collections.Generic;

class GfG {
    static bool wordBreak(string s, string[] dictionary)
    {
        int n = s.Length;
        bool[] dp = new bool[n + 1];
        dp[0] = true;

        // Traverse through the given string
        for (int i = 1; i <= n; i++) {

            // Traverse through the dictionary words
            foreach(string w in dictionary)
            {
                // Check if current word is present and the
                // prefix before the word is also breakable
                int start = i - w.Length;
                if (start >= 0 && dp[start]
                    && s.Substring(start, w.Length) == w) {
                    dp[i] = true;
                    break;
                }
            }
        }
        return dp[n];

    }

    public static void Main()
    {
        string s = "ilike";
        string[] dictionary = { "i", "like", "gfg" };

        Console.WriteLine(wordBreak(s, dictionary) ? "true" : "false");
    }
}
function wordBreak(s, dictionary)
{
    const n = s.length;
    const dp = new Array(n + 1).fill(false);
    dp[0] = true;

    // Traverse through the given string
    for (let i = 1; i <= n; i++) {

        // Traverse through the dictionary words
        for (const w of dictionary) {

            // Check if current word is present
            // the prefix before the word is also
            // breakable
            const start = i - w.length;
            if (start >= 0 && dp[start]
                && s.substring(start, start + w.length)
                       === w) {
                dp[i] = true;
                break;
            }
        }
    }
    return (dp[n]) ? 1 : 0;
}

const s = "ilike";
const dictionary = [ "i", "like", "gfg" ];

console.log(wordBreak(s, dictionary) ? "true" : "false");
Output
true
[Expected Approach] Trie and DP - O(n * L + m * L) Time and O(n + m * L) Space
In the earlier DP approaches, we compare every word (or every substring) at each position, which costs O(L) per check.
The idea is to store all dictionary words in a Trie, so that we can match many words at the same position in a single walk.
We do the following after building Trie,
- We start from index i and move forward character by character, and the walk stops as soon as no word shares the current prefix.
- Whenever we reach the end of a word, the position right after it becomes a valid break point.
Working of the Approach:
- Insert all dictionary words into a Trie, and mark the last node of each word as the end of a word.
- Create a boolean array dp[] of size n + 1, where dp[i] is true if the prefix s[0..i) can be broken into dictionary words.
- Mark dp[0] = true, as an empty prefix is always valid (base case).
- For each index i from 0 to n - 1, skip it if dp[i] is false, as no word can start from an unreachable position.
- If dp[i] is true, start from the root of the Trie and move along the characters s[i], s[i + 1], and so on.
- If the current character has no child in the Trie, stop, as no dictionary word has this prefix.
- If the current node marks the end of a word, set dp[j + 1] = true, where j is the index of the current character.
- At the end, return dp[n].
Let us understand with an example:
Input: s = "ilike", dictionary = ["i", "like", "gfg"]
- dp[0] = true, start from index 0 -> 'i' is the end of the word "i" -> dp[1] = true, next 'l' has no child -> stop
- dp[1] = true, start from index 1 -> l, i, k, e follow the word "like" -> 'e' is the end of a word -> dp[5] = true
- dp[2], dp[3], dp[4] are false, so they are skipped
- dp[5] = true, so the answer is true.
#include <iostream>
#include <vector>
#include <string>
using namespace std;

// trie node with 26 children, isEnd marks the end of a word
struct TrieNode {
    TrieNode* children[26];
    bool isEnd;

    TrieNode() {
        isEnd = false;
        for (int i = 0; i < 26; i++)
            children[i] = nullptr;
    }
};

// inserts a word into the trie
void insertWord(TrieNode* root, string &word) {
    TrieNode* curr = root;
    for (char c : word) {
        int idx = c - 'a';
        if (curr->children[idx] == nullptr)
            curr->children[idx] = new TrieNode();
        curr = curr->children[idx];
    }
    curr->isEnd = true;
}

bool wordBreak(string &s, vector<string> &dictionary) {
    int n = s.size();

    // insert all dictionary words into the trie
    TrieNode* root = new TrieNode();
    for (string &w : dictionary)
        insertWord(root, w);

    // dp[i] is true if s[0..i) can be broken into dictionary words
    vector<bool> dp(n + 1, false);

    // base case: an empty prefix is always valid
    dp[0] = true;

    // traverse through the given string
    for (int i = 0; i < n; i++) {

        // skip the position if no word can start from it
        if (!dp[i])
            continue;

        // walk down the trie starting from index i
        TrieNode* curr = root;
        for (int j = i; j < n; j++) {
            int idx = s[j] - 'a';

            // stop if no word has this prefix
            if (curr->children[idx] == nullptr)
                break;

            curr = curr->children[idx];

            // if a word ends here, mark the next position as valid
            if (curr->isEnd)
                dp[j + 1] = true;
        }
    }

    // the answer is stored at the last position
    return dp[n];
}

int main() {
    string s = "ilike";
    vector<string> dictionary = {"i", "like", "gfg"};

    cout << (wordBreak(s, dictionary) ? "true" : "false") << endl;
    return 0;
}
// trie node with 26 children, isEnd marks the end of a word
class TrieNode {
    TrieNode[] children = new TrieNode[26];
    boolean isEnd = false;
}

class GFG {

    // inserts a word into the trie
    static void insertWord(TrieNode root, String word) {
        TrieNode curr = root;
        for (char c : word.toCharArray()) {
            int idx = c - 'a';
            if (curr.children[idx] == null)
                curr.children[idx] = new TrieNode();
            curr = curr.children[idx];
        }
        curr.isEnd = true;
    }

    static boolean wordBreak(String s, String[] dictionary) {
        int n = s.length();

        // insert all dictionary words into the trie
        TrieNode root = new TrieNode();
        for (String w : dictionary)
            insertWord(root, w);

        // dp[i] is true if s[0..i) can be broken into dictionary words
        boolean[] dp = new boolean[n + 1];

        // base case: an empty prefix is always valid
        dp[0] = true;

        // traverse through the given string
        for (int i = 0; i < n; i++) {

            // skip the position if no word can start from it
            if (!dp[i])
                continue;

            // walk down the trie starting from index i
            TrieNode curr = root;
            for (int j = i; j < n; j++) {
                int idx = s.charAt(j) - 'a';

                // stop if no word has this prefix
                if (curr.children[idx] == null)
                    break;

                curr = curr.children[idx];

                // if a word ends here, mark the next position as valid
                if (curr.isEnd)
                    dp[j + 1] = true;
            }
        }

        // the answer is stored at the last position
        return dp[n];
    }

    public static void main(String[] args) {
        String s = "ilike";
        String[] dictionary = {"i", "like", "gfg"};

        System.out.println(wordBreak(s, dictionary));
    }
}
# trie node with 26 children, isEnd marks the end of a word
class TrieNode:
    def __init__(self):
        self.children = [None] * 26
        self.isEnd = False


# inserts a word into the trie
def insertWord(root, word):
    curr = root
    for c in word:
        idx = ord(c) - ord('a')
        if curr.children[idx] is None:
            curr.children[idx] = TrieNode()
        curr = curr.children[idx]
    curr.isEnd = True


def wordBreak(s, dictionary):
    n = len(s)

    # insert all dictionary words into the trie
    root = TrieNode()
    for w in dictionary:
        insertWord(root, w)

    # dp[i] is true if s[0..i) can be broken into dictionary words
    dp = [False] * (n + 1)

    # base case: an empty prefix is always valid
    dp[0] = True

    # traverse through the given string
    for i in range(n):

        # skip the position if no word can start from it
        if not dp[i]:
            continue

        # walk down the trie starting from index i
        curr = root
        for j in range(i, n):
            idx = ord(s[j]) - ord('a')

            # stop if no word has this prefix
            if curr.children[idx] is None:
                break

            curr = curr.children[idx]

            # if a word ends here, mark the next position as valid
            if curr.isEnd:
                dp[j + 1] = True

    # the answer is stored at the last position
    return dp[n]


if __name__ == "__main__":
    s = "ilike"
    dictionary = ["i", "like", "gfg"]

    print("true" if wordBreak(s, dictionary) else "false")
using System;

// trie node with 26 children, isEnd marks the end of a word
class TrieNode {
    public TrieNode[] children = new TrieNode[26];
    public bool isEnd = false;
}

class GFG {

    // inserts a word into the trie
    static void insertWord(TrieNode root, string word) {
        TrieNode curr = root;
        foreach (char c in word) {
            int idx = c - 'a';
            if (curr.children[idx] == null)
                curr.children[idx] = new TrieNode();
            curr = curr.children[idx];
        }
        curr.isEnd = true;
    }

    static bool wordBreak(string s, string[] dictionary) {
        int n = s.Length;

        // insert all dictionary words into the trie
        TrieNode root = new TrieNode();
        foreach (string w in dictionary)
            insertWord(root, w);

        // dp[i] is true if s[0..i) can be broken into dictionary words
        bool[] dp = new bool[n + 1];

        // base case: an empty prefix is always valid
        dp[0] = true;

        // traverse through the given string
        for (int i = 0; i < n; i++) {

            // skip the position if no word can start from it
            if (!dp[i])
                continue;

            // walk down the trie starting from index i
            TrieNode curr = root;
            for (int j = i; j < n; j++) {
                int idx = s[j] - 'a';

                // stop if no word has this prefix
                if (curr.children[idx] == null)
                    break;

                curr = curr.children[idx];

                // if a word ends here, mark the next position as valid
                if (curr.isEnd)
                    dp[j + 1] = true;
            }
        }

        // the answer is stored at the last position
        return dp[n];
    }

    static void Main() {
        string s = "ilike";
        string[] dictionary = {"i", "like", "gfg"};

        Console.WriteLine(wordBreak(s, dictionary) ? "true" : "false");
    }
}
// trie node with 26 children, isEnd marks the end of a word
class TrieNode {
    constructor() {
        this.children = new Array(26).fill(null);
        this.isEnd = false;
    }
}

// inserts a word into the trie
function insertWord(root, word) {
    let curr = root;
    for (let c of word) {
        let idx = c.charCodeAt(0) - 'a'.charCodeAt(0);
        if (curr.children[idx] === null)
            curr.children[idx] = new TrieNode();
        curr = curr.children[idx];
    }
    curr.isEnd = true;
}

function wordBreak(s, dictionary) {
    let n = s.length;

    // insert all dictionary words into the trie
    let root = new TrieNode();
    for (let w of dictionary)
        insertWord(root, w);

    // dp[i] is true if s[0..i) can be broken into dictionary words
    let dp = new Array(n + 1).fill(false);

    // base case: an empty prefix is always valid
    dp[0] = true;

    // traverse through the given string
    for (let i = 0; i < n; i++) {

        // skip the position if no word can start from it
        if (!dp[i])
            continue;

        // walk down the trie starting from index i
        let curr = root;
        for (let j = i; j < n; j++) {
            let idx = s.charCodeAt(j) - 'a'.charCodeAt(0);

            // stop if no word has this prefix
            if (curr.children[idx] === null)
                break;

            curr = curr.children[idx];

            // if a word ends here, mark the next position as valid
            if (curr.isEnd)
                dp[j + 1] = true;
        }
    }

    // the answer is stored at the last position
    return dp[n];
}

// Driver Code
let s = "ilike";
let dictionary = ["i", "like", "gfg"];

console.log(wordBreak(s, dictionary) ? "true" : "false");
Output
true
