

Backpropagation is an algorithm that trains neural networks by reducing prediction error. It works by propagating errors backward, computing gradients using the chain rule and updating weights and biases to improve performance.
- Computes gradients of the loss function with respect to each weight using the chain rule
- Updates weights and biases efficiently to reduce error
- Scales well to deep and complex neural networks
- Enables automatic learning and continuous improvement across training iterations

Working of Back Propagation Algorithm
The Back Propagation algorithm involves two main steps:
1. Forward Pass Work
In forward pass, input data moves through the network to generate an output.
- Input data is passed to the input layer and forwarded to hidden layers
- Each neuron computes a weighted sum and adds a bias
- Activation functions (like ReLU) are applied to produce outputs
- Outputs from one layer become inputs to the next layer
- Final layer uses functions like softmax to produce predictions (e.g., probabilities for classification)

2. Backward Pass
In this step, the error between predicted and actual output is propagated backward to update weights and biases. Error is calculated (e.g., using Mean Squared Error)
\text{MSE} = (\text{Predicted Output} - \text{Actual Output})^2
- Gradients are computed using the chain rule
- Weights and biases are updated to reduce the error
- Process continues layer by layer from output to input
- Derivatives of activation functions are used to compute gradients effectively
Example
Let’s walk through an example of Back Propagation in machine learning. Assume the neurons use the sigmoid activation function for the forward and backward pass. The target output is 0.5 and the learning rate is 1.

Forward Propagation
1. Initial Calculation
The weighted sum at each node is calculated using:
a _j =∑(w_i ,j∗x _i )
Where,
a_j is the weighted sum of all the inputs and weights at each nodew_{i,j} represents the weights between thei^{th} input and thej^{th} neuronx_i represents the value of thei^{th} input
O (output): After applying the activation function to a, we get the output of the neuron:
o_j = activation function(a_j )
2. Sigmoid Function
The sigmoid function returns a value between 0 and 1, introducing non-linearity into the model.
y_j = \frac{1}{1+e^{-a_j}}

3. Computing Outputs
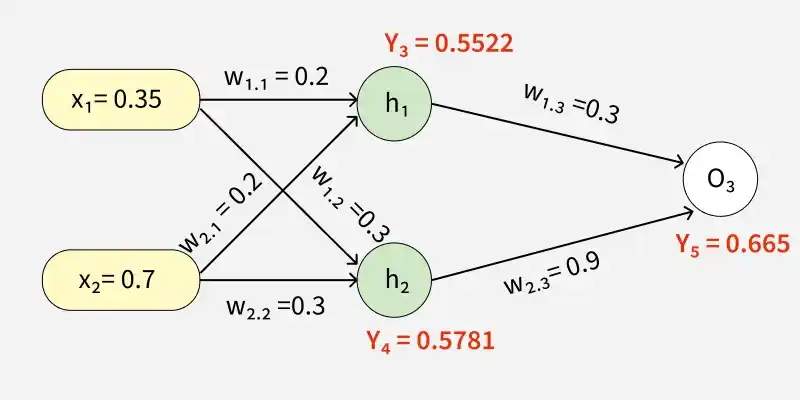
At h1 node
\begin {aligned}a_1 &= (w_{1,1} x_1) + (w_{2,1} x_2) \\& = (0.2 * 0.35) + (0.2* 0.7)\\&= 0.21\end {aligned}
Once we calculated the a1 value, we can now proceed to find the y3 value:
y_j= F(a_j) = \frac 1 {1+e^{-a_1}}
y_3 = F(0.21) = \frac 1 {1+e^{-0.21}}
y_3 = 0.5522
Similarly find the values of y4 at h2 and y5 at O3
a_2 = (w_{1,2} * x_1) + (w_{2,2} * x_2) = (0.3*0.35)+(0.3*0.7)=0.315
y_4 = F(0.315) = \frac 1{1+e^{-0.315}} = 0.5781
a_3 = (w_{1,3}*y_3)+(w_{2,3}*y_4) =(0.3*0.5522)+(0.9*0.5781) =0.686
y_5 = F(0.686) = \frac 1 {1+e^{-0.686} } = 0.665
4. Error Calculation
Our actual output is 0.5 but we obtained 0.67. To calculate the error we can use the below formula:
Error_j= y_{target} - y_5
\text{=>} \space 0.5 - 0.665 = -0.165
Using this error value we will be backpropagating.
Back Propagation Calculation
1. Calculating Gradients
The change in each weight is calculated as:
\Delta w_{ij} = \eta \times \delta_j \times O_j
Where:
\delta_j is the error term for each unit,\eta is the learning rate.
2. Output Unit Error
For O3:
\delta_5 = y_5(1-y_5) (y_{target} - y_5)
= 0.665(1-0.665)(-0.165) = -0.0367
3. Hidden Unit Error
For h1:
\delta_3 = y_3 (1-y_3)(w_{1,3} \times \delta_5)
= 0.5522(1-0.5522)(0.3 \times -0.0367) = -0.00273
For h2:
\delta_4 = y_4(1-y_4)(w_{2,3} \times \delta_5)
=0.5781 (1-0.5781)(0.9 \times -0.0367) = -0.0080
4. Weight Updates
The general formula is:
Therefore:
\Delta w_{1,3}=\eta\delta_5y_3 \Delta w_{2,3}=\eta\delta_5y_4
For
\Delta w_{1,3} = 1\times(-0.0367)\times0.5522 \approx-0.0203 :
w_{1,3}(\text{new}) = 0.3+(-0.0203) w_{1,3}\approx0.2797
For
\Delta w_{2,3} = 1 \times (-0.0367) \times 0.5781 = -0.0212
w_{2,3}(\text{new}) = -0.0212 + 0.9 = 0.8788
For the weights from the input layer to the hidden layer:
\Delta w_{1,1}=\eta\delta_3x_1 \\ \Delta w_{2,1}=\eta\delta_3x_2 \\ \Delta w_{1,2}=\eta\delta_4x_1 \\ \Delta w_{2,2}=\eta\delta_4x_2 \\
Using:
For
\Delta w_{1,1} = 1\times(-0.00273)\times0.35 \approx-0.00096
w_{1,1}(\text{new}) = 0.2+(-0.00096) \approx0.19904
For
\Delta w_{2,1} = 1\times(-0.00273)\times0.7 \approx-0.00191
w_{2,1}(\text{new}) = 0.2+(-0.00191) \approx0.19809
For
\Delta w_{1,2} = 1\times(-0.0080)\times0.35 \approx-0.00280
w_{1,2}(\text{new}) = 0.3+(-0.00280) \approx0.29720
For
\Delta w_{2,2} = 1\times(-0.0080)\times0.7 \approx-0.00560
w_{2,2}(\text{new}) = 0.3+(-0.00560) \approx0.29440
Updated weights:
w_{1,1}=0.19904 \\ w_{2,1}=0.19809 \\ w_{1,2}=0.29720 \\ w_{2,2}=0.29440 \\ w_{1,3}=0.27970 \\ w_{2,3}=0.87880 \\
The update rule follows the standard backpropagation formula: each weight change equals the learning rate multiplied by the receiving neuron’s delta and the sending neuron’s output.
The updated weights are illustrated below
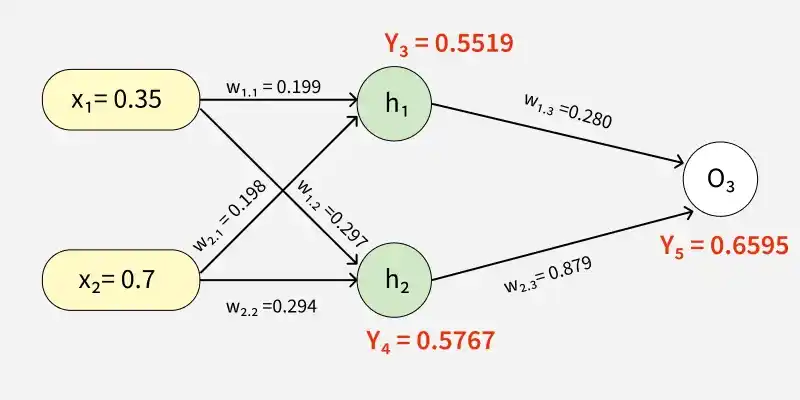
After updating the weights, the forward pass is repeated, hence giving:
y_3 \approx 0.5519 \\ y_4 \approx 0.5767 \\ y_5 \approx 0.6595
Since
This process demonstrates how backpropagation iteratively updates weights by minimizing the error.
\text{Error}=y_{\text{target}}-y_5 =0.5-0.6595\approx-0.1595
This process continues until the network’s output becomes sufficiently close to the target output.
Implementation
This code demonstrates how Back Propagation is used in a neural network to solve the XOR problem. The neural network consists of:
1. Defining Neural Network
The network consists of 2 input neurons, 4 hidden neurons and 1 output neuron, using the sigmoid activation function.
- input_size and hidden_size define the layer sizes
- weights_input_hidden initializes weights from input to hidden layer
- weights_hidden_output initializes weights from hidden to output layer
- bias_hidden and bias_output initialize bias terms for respective layers
import numpy as np


class NeuralNetwork:
    def __init__(self, input_size, hidden_size, output_size):
        self.input_size = input_size
        self.hidden_size = hidden_size
        self.output_size = output_size

        self.weights_input_hidden = np.random.randn(
            self.input_size, self.hidden_size)
        self.weights_hidden_output = np.random.randn(
            self.hidden_size, self.output_size)

        self.bias_hidden = np.zeros((1, self.hidden_size))
        self.bias_output = np.zeros((1, self.output_size))

    def sigmoid(self, x):
        return 1 / (1 + np.exp(-x))

    def sigmoid_derivative(self, x):
        return x * (1 - x)
2. Defining Feed Forward Network
In Forward pass inputs are passed through the network activating the hidden and output layers using the sigmoid function.
- Computes hidden layer activation using weighted sum and bias
- Applies sigmoid to get hidden layer output
- Computes output layer activation from hidden outputs
- Applies sigmoid to produce final predicted output
def feedforward(self, X):
    self.hidden_activation = np.dot(
        X, self.weights_input_hidden) + self.bias_hidden
    self.hidden_output = self.sigmoid(self.hidden_activation)

    self.output_activation = np.dot(
        self.hidden_output, self.weights_hidden_output) + self.bias_output
    self.predicted_output = self.sigmoid(self.output_activation)

    return self.predicted_output
3. Defining Backward Network
In the backward pass, the network calculates the error and updates weights using gradients from the sigmoid function.
- Computes output error as difference between actual and predicted values
- Calculates output delta using sigmoid derivative
- Propagates error to hidden layer using dot product
- Computes hidden delta using sigmoid derivative
- Updates weights between hidden output and input hidden layers
def backward(self, X, y, learning_rate):
    output_error = y - self.predicted_output
    output_delta = output_error * \
        self.sigmoid_derivative(self.predicted_output)

    hidden_error = np.dot(output_delta, self.weights_hidden_output.T)
    hidden_delta = hidden_error * self.sigmoid_derivative(self.hidden_output)

    self.weights_hidden_output += np.dot(self.hidden_output.T,
                                         output_delta) * learning_rate
    self.bias_output += np.sum(output_delta, axis=0,
                               keepdims=True) * learning_rate
    self.weights_input_hidden += np.dot(X.T, hidden_delta) * learning_rate
    self.bias_hidden += np.sum(hidden_delta, axis=0,
                               keepdims=True) * learning_rate
4. Training Network
The network is trained over 10,000 epochs using the Back Propagation algorithm with a learning rate of 0.1 progressively reducing the error.
- output = self.feedforward(X): computes the output for the current inputs
- self.backward(X, y, learning_rate): updates weights and biases using Back Propagation
- loss = np.mean(np.square(y - output)): calculates the mean squared error (MSE) loss
def train(self, X, y, epochs, learning_rate):
    for epoch in range(epochs):
        output = self.feedforward(X)
        self.backward(X, y, learning_rate)
        if epoch % 4000 == 0:
            loss = np.mean(np.square(y - output))
            print(f"Epoch {epoch}, Loss:{loss}")
5. Testing Neural Network
- X = np.array([[0, 0], [0, 1], [1, 0], [1, 1]]): defines the input data
- y = np.array([[0], [1], [1], [0]]): defines the target values
- nn = NeuralNetwork(input_size=2, hidden_size=4, output_size=1): initializes the neural network
- nn.train(X, y, epochs=10000, learning_rate=0.1): trains the network
- output = nn.feedforward(X): gets the final predictions after training
X = np.array([[0, 0], [0, 1], [1, 0], [1, 1]])
y = np.array([[0], [1], [1], [0]])

nn = NeuralNetwork(input_size=2, hidden_size=4, output_size=1)
nn.train(X, y, epochs=10000, learning_rate=0.1)

output = nn.feedforward(X)
print("Predictions after training:")
print(output)
Output:

Download full code from here
Advantages
- Easy to implement and beginner-friendly, as it updates weights using error derivatives
- Simple and flexible, making it suitable for different types of networks like feedforward, CNNs and RNNs
- Efficient in learning, as it directly adjusts weights based on error, especially in deep networks
- Helps models generalize well, improving performance on unseen data
- Scales effectively with large datasets and complex architectures
Challenges
- Gradients can become very small in deep networks, making learning slow or difficult (vanishing gradient problem)
- Gradients can grow too large, causing unstable training and divergence (exploding gradients)
- Complex models may overfit the training data instead of learning general patterns
