

Cross-attention mechanism is a key part of the Transformer model. It allows the decoder to access and use relevant information from the encoder. This helps the model focus on important details, ensuring tasks like translation are accurate.
Suppose generating captions for images (decoder) from a detailed description (encoder). Cross-attention helps the caption generator focus on key details, ensuring accuracy in the caption.
Cross-attention enables different parts of the model to communicate and share useful information for better results.
Working
Cross-attention connects the encoder and decoder by using the decoder's representations as queries and the encoder's representations as keys and values.
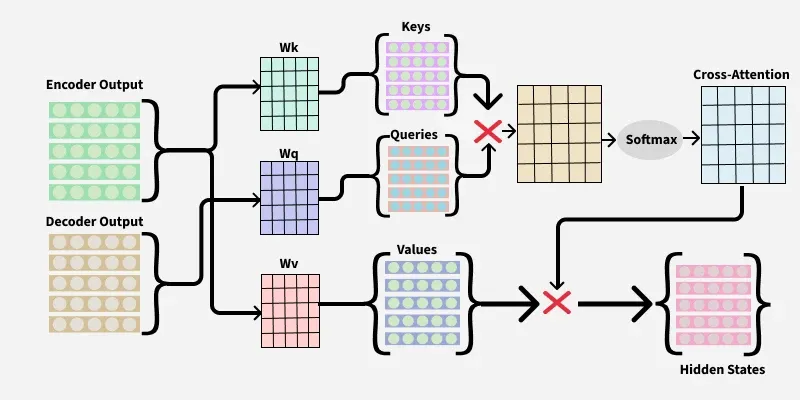
The process can be understood as follows:
- Encoder: The encoder processes the input sequence and produces a representation for each input token.
- Decoder: The decoder processes the previously generated tokens and produces a query for the next output.
- Query-Key Matching: The decoder's query is compared with the encoder's keys to determine which input tokens are most relevant.
- Weighted Information: The resulting attention weights are applied to the encoder's values to create a context representation.
- Output Generation: The decoder uses this context along with its own representation to generate the next token.
In the above image, the first red cross represents the dot product between the queries and keys, while the second red cross represents the multiplication of the attention weights with the values.
For example, when translating "I like eating ice cream" into another language, cross-attention helps the system understand that "ice cream" is important and should be translated correctly.
Mathematical Expression
Cross-attention uses the same scaled dot-product attention mechanism as self-attention. The main difference is the source of the queries, keys and values.
\text{Attention}(Q, K, V) = \text{softmax}\left(\frac{QK^T}{\sqrt{d_k}}\right) V
Where:
- Q (Query): Comes from the decoder.
- K (Key): Comes from the encoder.
- V (Value): Comes from the encoder.
- (dk): Dimension of the key vectors.
The multiplication (QKT) produces attention scores that indicate how strongly each decoder position should attend to each encoder position.
Complexity of Cross-Attention
The computational cost of cross-attention depends on the lengths of the query and key/value sequences.
Let:
- (nq) = length of the decoder sequence
- (nk) = length of the encoder sequence
- (d) = dimension of the attention vectors
Time Complexity
The time complexity of cross-attention is:
O(n_q n_k d)
This is because each of the (nq) queries is compared with all (nk) keys and each comparison involves (d)-dimensional vectors.
Space Complexity
The attention score matrix has a size of
(n_q \times n_k) . Therefore, its space complexity is:O(n_q n_k)
As either sequence becomes longer, the computational and memory requirements increase. Techniques such as sparse attention and efficient attention can reduce these costs for long sequences.
Applications
- Machine Translation: The decoder attends to the source-language representation while generating the target-language sequence.
- Text Summarization: The decoder attends to the input document to identify information relevant to the summary.
- Question Answering: A model can use cross-attention to relate a question to a passage and identify relevant information.
- Image Captioning: The text decoder can attend to visual features extracted from an image while generating a caption.
- Speech Recognition: A decoder can attend to encoded speech representations while generating the corresponding text.
Cross-Attention vs. Self-Attention
| Aspect | Cross-Attention | Self-Attention |
|---|---|---|
| Definition | Allows one sequence to attend to another sequence. | Allows tokens within the same sequence to attend to one another. |
| Query (Q) | Usually comes from the decoder or target sequence. | Comes from the same sequence as K and V. |
| Key and Value (K, V) | Usually come from the encoder or source sequence. | Come from the same sequence as Q. |
| Purpose | Connects information from different sequences or representations. | Captures relationships within a sequence. |
| Example | A decoder attending to an encoded source sentence during translation. | A token attending to other tokens in the same sentence. |
| Data Flow | Information flows between two representations. | Information is exchanged within one representation. |
