

Word Embeddings are numeric representations of words in a lower-dimensional space, that capture semantic and syntactic information. They play a important role in Natural Language Processing (NLP) tasks.
Word embeddings are dense numerical vectors that represent words in a continuous vector space, where words used in similar contexts tend to have similar representations.
- Method of extracting features out of text so that we can input those features into a machine learning model to work with text data.
- It allows words with similar meanings to have a similar representation. Thus, Similarity can be assessed based on Similar vector representations.
- Preserve syntactical and semantic information.
- Some methods based on Word Frequency are Bag of Words (BOW), Count Vectorizer and TF-IDF.
Usage
- They are used as input to machine learning models.
Words ----> Numeric representation ----> Use in Training or Inference.
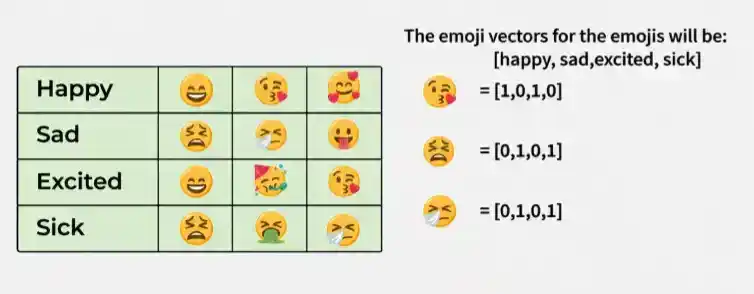
- To represent or visualize any underlying patterns of usage in the corpus that was used to train them.
Similar words tend to have similar vectors.
Approaches for Text Representation
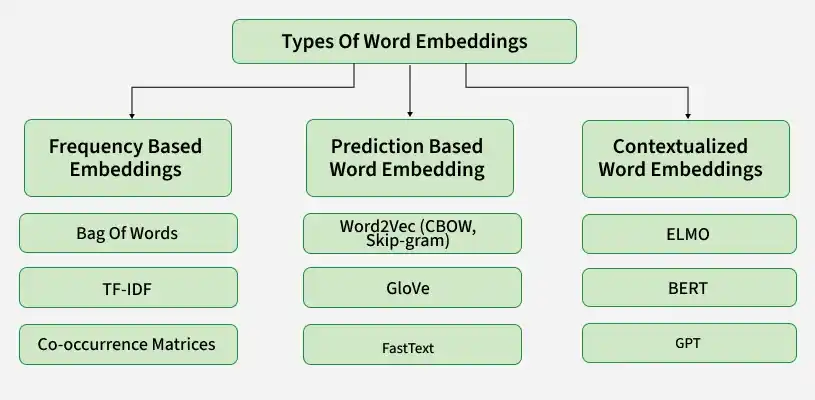
1. Traditional Approach
The conventional method assigns each distinct vocabulary word a unique ID and uses these IDs to represent words in a sentence. Since every vocabulary word becomes a feature, a large vocabulary results in a high-dimensional feature space.
2. Neural Approach
2.1 Word2Vec
Word2Vec is a neural approach for generating word embeddings. It belongs to the family of neural word embedding techniques and specifically falls under the category of distributed representation models. It is a popular technique in natural language processing (NLP).
- Represent words as continuous vector spaces.
- Aim: Capture the semantic relationships between words by mapping them to high-dimensional vectors.
- Words with similar meanings should have similar vector representations. Every word is assigned a vector. We start with either a random or one-hot vector.
There are two neural embedding methods for Word2Vec: Continuous Bag of Words (CBOW) and Skip-gram.
2.2 Continuous Bag of Words(CBOW)
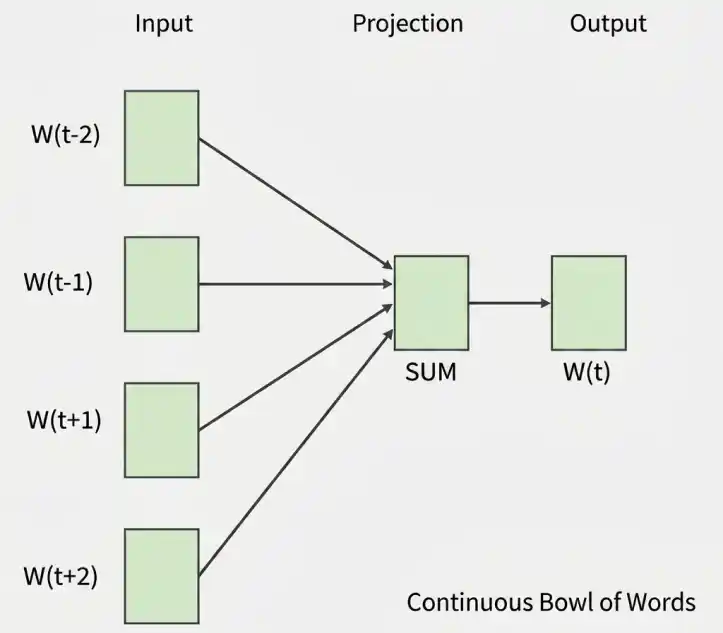
Continuous Bag of Words (CBOW) is a neural architecture used in Word2Vec to predict a target word from its surrounding context within a given window.
import torch
import torch.nn as nn
import torch.optim as optim

# Define CBOW model
class CBOWModel(nn.Module):
    def __init__(self, vocab_size, embed_size):
        super(CBOWModel, self).__init__()
        self.embeddings = nn.Embedding(vocab_size, embed_size)
        self.linear = nn.Linear(embed_size, vocab_size)

    def forward(self, context):
      context_embeds = self.embeddings(context)
      context_embeds = context_embeds.sum(dim=0)
      output = self.linear(context_embeds)
      return output

context_size = 2
raw_text = "word embeddings are useful for natural language processing"
tokens = raw_text.split()
vocab = set(tokens)
word_to_index = {word: i for i, word in enumerate(vocab)}
data = []
for i in range(context_size, len(tokens) - context_size):
    context = [word_to_index[word] for word in tokens[i - context_size:i] + tokens[i + 1:i + context_size + 1]]
    target = word_to_index[tokens[i]]
    data.append((torch.tensor(context), torch.tensor(target)))

# Hyperparameters
vocab_size = len(vocab)
embed_size = 10
learning_rate = 0.01
epochs = 100

# Initialize CBOW model
cbow_model = CBOWModel(vocab_size, embed_size)
criterion = nn.CrossEntropyLoss()
optimizer = optim.SGD(cbow_model.parameters(), lr=learning_rate)

# Training loop
for epoch in range(epochs):
    total_loss = 0
    for context, target in data:
        optimizer.zero_grad()
        output = cbow_model(context)
        loss = criterion(output.unsqueeze(0), target.unsqueeze(0))
        loss.backward()
        optimizer.step()
        total_loss += loss.item()
    print(f"Epoch {epoch + 1}, Loss: {total_loss}")

# Example usage
word_to_lookup = "embeddings"
word_index = word_to_index[word_to_lookup]
embedding = cbow_model.embeddings(torch.tensor([word_index]))
print(f"Embedding for '{word_to_lookup}': {embedding.detach().numpy()}")
Output:
Epoch 1, Loss: 12.933784246444702 ........ Epoch 100, Loss: 0.24656445160508156
Embedding for 'embeddings': [[ 0.7754499 -0.51582754 -1.1221999 -0.52298266 -0.34923297 1.3705542 2.0377991 -1.0031306 -2.2332792 0.6363237 ]]
This code builds and trains a CBOW model to predict target words from their surrounding context and then extracts the learned embedding for "embeddings".
2.3 Skip-Gram
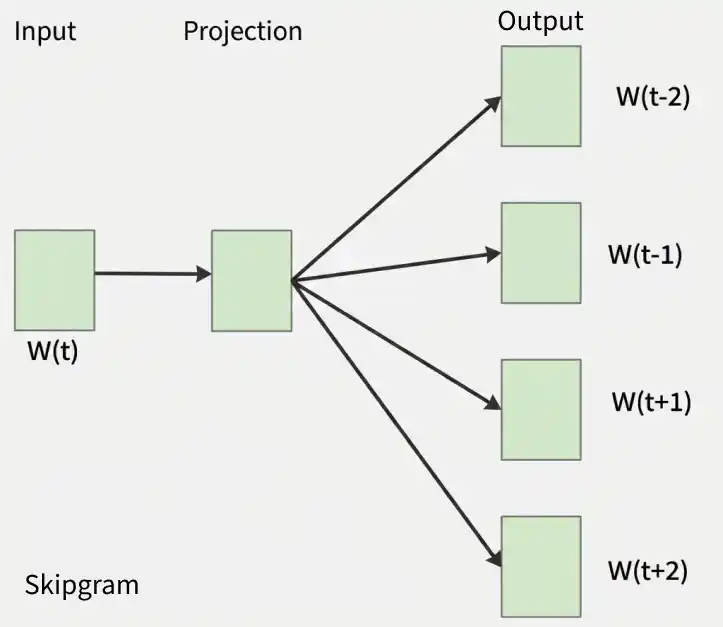
The Skip-Gram model is a Word2Vec architecture that predicts surrounding context words from a target word. It is the opposite of CBOW, which predicts the target word from its context.
- Output: Trained vectors of each word after many iterations through the corpus.
- Preserve syntactical or semantic information, Converted to lower dimensions.
- Similar meaning (semantic info) vectors are placed close to each other in space.
- vector_size parameter controls the dimensionality of the word vectors and you can adjust other parameters such as window.
Note: Word2Vec models can perform better with larger datasets. If you have a large corpus, you might achieve more meaningful word embeddings.
!pip install gensim
from gensim.models import Word2Vec
from nltk.tokenize import word_tokenize
import nltk
nltk.download('punkt')
nltk.download('punkt_tab')

sample = "Word embeddings are dense vector representations of words."
tokenized_corpus = word_tokenize(sample.lower())

skipgram_model = Word2Vec(sentences=[tokenized_corpus],
                          vector_size=100,
                          window=5,
                          sg=1,
                          min_count=1,
                          workers=4,
                          epochs=10)

skipgram_model.save("skipgram_model.model")
loaded_model = Word2Vec.load("skipgram_model.model")
vector_representation = loaded_model.wv['word']
print("Vector representation of 'word':", vector_representation)
Output:
Vector representation of 'word': [-9.5785465e-03 8.9431154e-03 ...
... 5.8914376e-03 -5.5806171e-03]
This code trains a Skip-Gram Word2Vec model and extracts the 100-dimensional vector representation of the word "word".
The choice between CBOW and Skip-gram depends on data and the task. CBOW is generally faster to train, while Skip-Gram can perform well for rare words and semantic relationships.
3. Pretrained Word-Embedding
Pre-trained word embeddings are word representations learned from large text corpora and reused for various NLP tasks. They capture semantic relationships and similarities between words.
3.1 GloVe
GloVe learns word vectors from global word-word co-occurrence statistics. It builds a co-occurrence matrix showing how often words appear together, then learns vectors that capture these patterns.
Matrix Creation: Corpus
It is a nice evening.
Good Evening!
Is it a nice evening?
| it | is | a | nice | evening | good | |
|---|---|---|---|---|---|---|
| it | 0 | |||||
| is | 1+1 | 0 | ||||
| a | 1/2+1 | 1+1/2 | 0 | |||
| nice | 1/3+1/2 | 1/2+1/3 | 1+1 | 0 | ||
| evening | 1/4+1/3 | 1/3+1/4 | 1/2+1/2 | 1+1 | 0 | |
| good | 0 | 0 | 0 | 0 | 1 | 0 |
The upper and lower halves of the matrix are symmetric. A sliding window can be used to count word co-occurrences across the corpus, capturing the context in which each word appears.
3.2 Fasttext
FastText extends Word2Vec by representing words using character n-grams. This helps capture morphological information and allows representations to be generated for previously unseen words.
import gensim.downloader as api
fasttext_model = api.load("fasttext-wiki-news-subwords-300") ## Load the pre-trained fastText model

word_pairs = [('learn', 'learning'), ('india', 'indian'), ('fame', 'famous')]

# Compute similarity for each pair of words
for pair in word_pairs:
    similarity = fasttext_model.similarity(pair[0], pair[1])
    print(f"Similarity between '{pair[0]}' and '{pair[1]}' using FastText: {similarity:.3f}")
Output:
Similarity between 'learn' and 'learning' using FastText: 0.642
Similarity between 'india' and 'indian' using FastText: 0.708
Similarity between 'fame' and 'famous' using FastText: 0.519
This code uses a pretrained FastText model to calculate the cosine similarity between related word pairs.
3.3 BERT (Bidirectional Encoder Representations from Transformers)
BERT can provide contextual word representations.
You can download the complete source code from here.
Comparison of Text Representations & Word Embeddings
| Representation | Dense/Sparse | Captures Semantic Similarity? |
|---|---|---|
| One-Hot | Sparse | No |
| BoW | Sparse | No |
| TF-IDF | Sparse | Limited |
| Word2Vec | Dense | Yes |
| GloVe | Dense | Yes |
| FastText | Dense | Yes |
Static vs. Contextual Word Embeddings
| Feature | Static Embeddings | Contextual Embeddings |
|---|---|---|
| Representation | One vector per word | Depends on context |
| Examples | Word2Vec, GloVe, FastText | ELMo, BERT |
| Handles polysemy | Limited | Better |
| Training approach | Word/context statistics | Deep language-model pretraining |
Considerations for Deploying Word Embedding Models
- You need to use the exact same pipeline during deploying your model as were used to create the training data for the word embedding.
- Use subword-based methods such as FastText when handling rare or unseen words is important.
Measuring Similarity Between Word Embeddings
Cosine similarity measures how similar two non-zero vectors are by finding the cosine of the angle between them.
\text{cosine similarity}(A,B)=\frac{A\cdot B}{\|A\|\|B\|}
A value closer to 1 indicates that the vectors point in similar directions.
Advantages
- Capture semantic and syntactic relationships in dense vectors.
- Reduce the dimensionality of vocabulary-based representations.
- Can be reused across multiple NLP tasks.
- Pretrained embeddings reduce the need to learn representations from scratch.
Limitations
- Static embeddings are context-independent: Word2Vec/GloVe assign one vector to a word, so polysemous words such as "bank" have one representation.
- Corpus bias: learned vectors can reflect biases in training data.
- Out-of-vocabulary words: traditional Word2Vec/GloVe cannot directly produce vectors for unseen words; FastText handles this better through subwords.
- Domain dependence: embeddings trained on one domain may not work equally well in another.
- Embedding size and storage: large vocabularies can require substantial memory.
