

Masked Language Models (MLMs) are language models trained to predict tokens that are intentionally hidden or masked in a text sequence. They learn language patterns and contextual relationships by using the surrounding words.
- MLMs use surrounding context to predict masked tokens.
- They are mainly used for language understanding and representation learning.
- BERT, RoBERTa and ALBERT are popular examples of models that use masked language modeling.
Working
The process of training a masked language model involves two main steps:
1. Masking Tokens
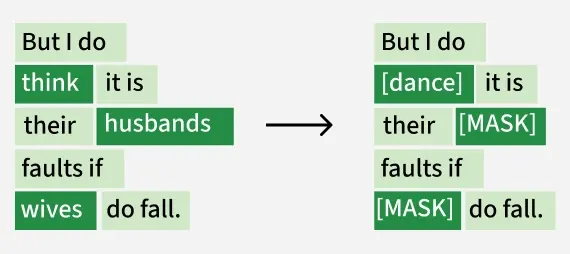
During training, the model is presented with sentences where some words are randomly replaced with a special token, such as "[MASK]." In the below example, two words have been replaced with mask tokens while another word replaced by different word token.
2. Predicting Missing Words
The model is then tasked with predicting the original word that was masked. It does this by analyzing the surrounding words in the sentence. Using the above example, the model would predict "books" based on the context provided by "reads" and "every evening."
This process is repeated millions of times across vast amounts of text data and allow the model to learn patterns, grammar and semantic relationships in language.
3. Learning Contextual Representations
The model learns that the meaning of a word can change depending on its surrounding context.
For example: She deposited money in the [MASK].
Here, the model can infer that "bank" refers to a financial institution.
In another sentence: They sat on the river [MASK].
The same word refers to the land beside a river.
Features
MLMs have played an important role in NLP because they allow models to learn useful language representations from large amounts of unlabeled text.
1. Bidirectional Context
MLMs such as BERT can use information from both sides of a masked token. This helps the model understand how words relate to the complete sentence.
2. Contextual Representations
MLMs represent words according to their context, allowing the same word to have different representations in different sentences.
3. Transfer Learning
A pretrained MLM can be fine-tuned for specific NLP tasks such as:
- Text Classification: Assigning categories such as positive, negative or neutral.
- Named Entity Recognition: Identifying people, organizations and locations.
- Question Answering: Extracting answers from a given passage.
- Information Extraction: Extracting relevant information from unstructured text.
Popular Masked Language Models
Several models fall under the category of masked language models. Here are a few examples:
- BERT (Bidirectional Encoder Representations from Transformers) : Developed by Google BERT is one of the most influential MLMs. It introduced the concept of bidirectional training and has been widely used for tasks like question answering, text summarization and sentiment analysis.
- RoBERTa (Robustly Optimized BERT Pretraining Approach) : An improved version of BERT RoBERTa uses more training data and optimizes the masking strategy to achieve better performance.
- ALBERT (A Lite BERT) : A lighter and more efficient version of BERT, ALBERT reduces the model size while maintaining high performance.
- DistilBERT : A smaller, faster version of BERT that retains most of its capabilities but requires fewer computational resources.
Applications
- Text Classification: MLMs can classify text into predefined categories, such as classifying customer reviews, news articles or support queries.
- Named Entity Recognition: MLMs can identify important entities in text, including people, organizations, locations, dates and products.
- Question Answering: MLM-based models can understand a question and identify the relevant answer from a given passage or document.
- Sentiment Analysis: MLMs can determine whether text expresses a positive, negative or neutral sentiment, making them useful for analyzing reviews and feedback.
- Domain-Specific NLP: MLMs can be adapted to specialized fields such as healthcare, finance, science and law to process domain-specific text.
Limitations
- Bias in Training Data : Since MLMs are trained on large datasets scraped from the internet, they can inadvertently learn and perpetuate biases present in the data.
- Computational Costs : Training large models like BERT requires significant computational resources, making it expensive and inaccessible for smaller organizations.
- Interpretability : The inner workings of MLMs can be difficult to interpret, raising concerns about transparency and accountability.
- Overfitting : If not properly regularized, MLMs may overfit to the training data, leading to poor generalization on unseen data.
