

Reliability in system design refers to the ability of a system to perform its intended functions consistently over a specified period under expected operating conditions.
- A reliable system aims to reduce unexpected failures and incorrect behavior.
- Reliability depends on system design, fault handling, monitoring, recovery mechanisms, and operational conditions.
Example: In an online banking system, reliability helps ensure that transactions are processed correctly and that failures do not result in data loss or inconsistent account states.
Factors That Affect System Reliability
Several factors influence how consistently a system operates without failure.
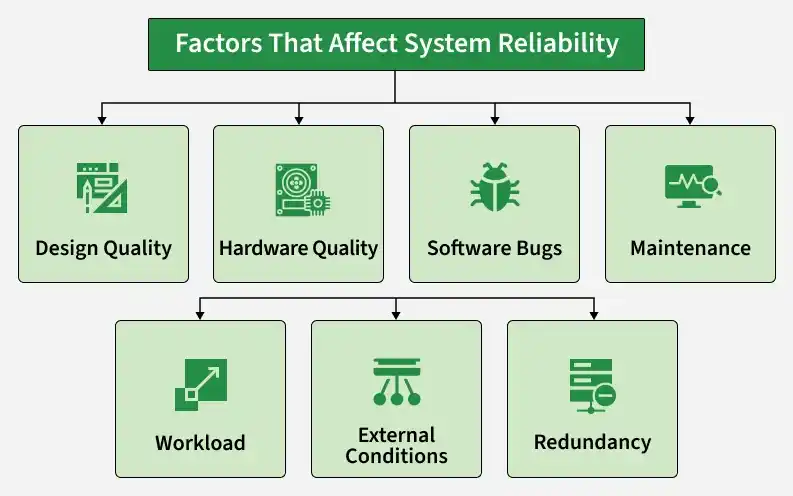
- Design Quality: Poor architecture or inadequate planning can increase the likelihood of failures.
- Hardware Reliability: Hardware faults in servers, disks, or networking components can disrupt system operation.
- Software Bugs: Coding or configuration errors can cause crashes, incorrect results, or unexpected behavior.
- Maintenance: Lack of updates, testing, monitoring, and preventive maintenance can reduce reliability.
- Workload: Operating beyond system capacity can cause performance degradation or failures.
- External Conditions: Power outages, network failures, or environmental conditions may affect operation.
- Redundancy and Failover: Backup components and failover mechanisms can reduce the impact of individual component failures.
Ways to Improve System Reliability
These approaches help systems remain stable, reduce failures, and maintain consistent performance under different conditions.
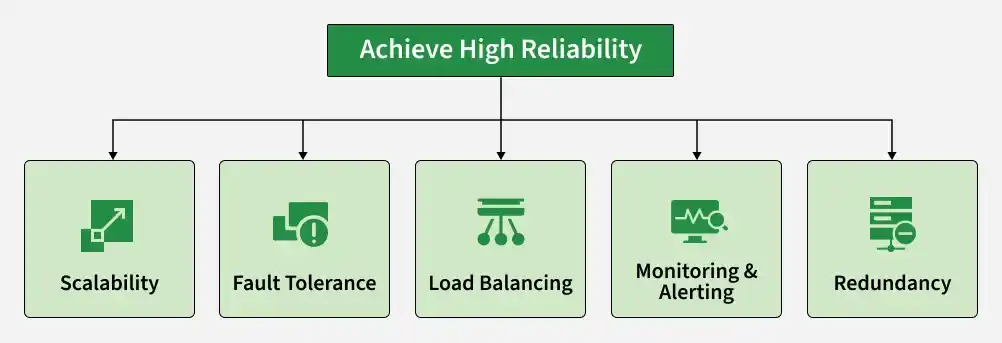
- Scalability: Helps prevent overload-related failures by allowing capacity to grow with workload.
- Fault Tolerance: Allows the system to continue operating when certain components fail.
- Load Balancing: Distributes workload across available resources to reduce overload.
- Monitoring and Alerting: Helps detect failures and abnormal behavior early.
- Redundancy: Provides backup components that can take over when primary components fail.
Ways to Measure Reliability
Reliability can be evaluated using failure-related and service-health metrics.
1. Mean Time Between Failures (MTBF)
MTBF measures the average operating time between failures in a repairable system.
MTBF = Total Operational Time / Number of Failures
Example: If a system operates for 1,000 hours and experiences 5 failures:
MTBF = 1000 / 5 = 200 hours
A higher MTBF generally indicates fewer failures over time.
2. Mean Time to Repair (MTTR)
MTTR measures the average time required to restore a failed system.
MTTR = Total Repair Time / Number of Repairs
Example: If 5 failures require a total of 10 hours to repair:
MTTR = 10 / 5 = 2 hours
A lower MTTR indicates faster recovery, which improves availability.
3. Error Rate
Error rate measures the percentage of operations or requests that fail.
Error Rate = (Number of Errors / Total Operations) × 100
Example: If 50 of 10,000 operations fail:
Error Rate = (50 / 10000) × 100 = 0.5%
4. Uptime Percentage
Uptime measures the percentage of time a service remains available.
Uptime = ((Total Time − Downtime) / Total Time) × 100
Example: If a system is unavailable for 2 hours during a 168-hour week:
Uptime = ((168 − 2) / 168) × 100 = 98.81%
Note: Uptime is primarily an availability metric, but it is often monitored alongside reliability metrics because frequent failures can reduce service availability.
Reasons for System Failures
Systems may become unreliable due to failures in design, software, hardware, resources, or external dependencies.
- Poor System Design: Weak architecture can create bottlenecks and fragile dependencies.
- Hardware Failures: Servers, disks, or network devices can fail unexpectedly.
- Software Bugs: Defects or configuration errors can cause incorrect behavior or crashes.
- Overloaded Systems: Traffic beyond system capacity can lead to degradation or failure.
- Network Issues: Packet loss, high latency, or connectivity failures can disrupt distributed components.
- Lack of Monitoring and Maintenance: Undetected problems can develop into larger failures.
- Single Point of Failure (SPOF): A critical component without redundancy can cause significant disruption if it fails.
